Abstract
LOCI is a hybrid spatial memory for streaming video world models. Half of the transformer blocks keep a key–value cache of past observations; the other half pair current-chunk attention with a recurrent linear-attention memory whose reads and writes are conditioned on camera geometry. On MIND and held-out recorded trajectories, LOCI reproduces revisited content more faithfully than representative world models, and with a bounded bank of retained observations it streams long videos at constant memory.
- +0.89dB
- PSNR over a same-recipe full-softmax model under an identical bounded KV budget (MIND, all 50 segments; better in 44 of 50)
- +1.82dB
- PSNR above the strongest streaming world model we run on MIND (HY-WorldPlay)
- ~30%
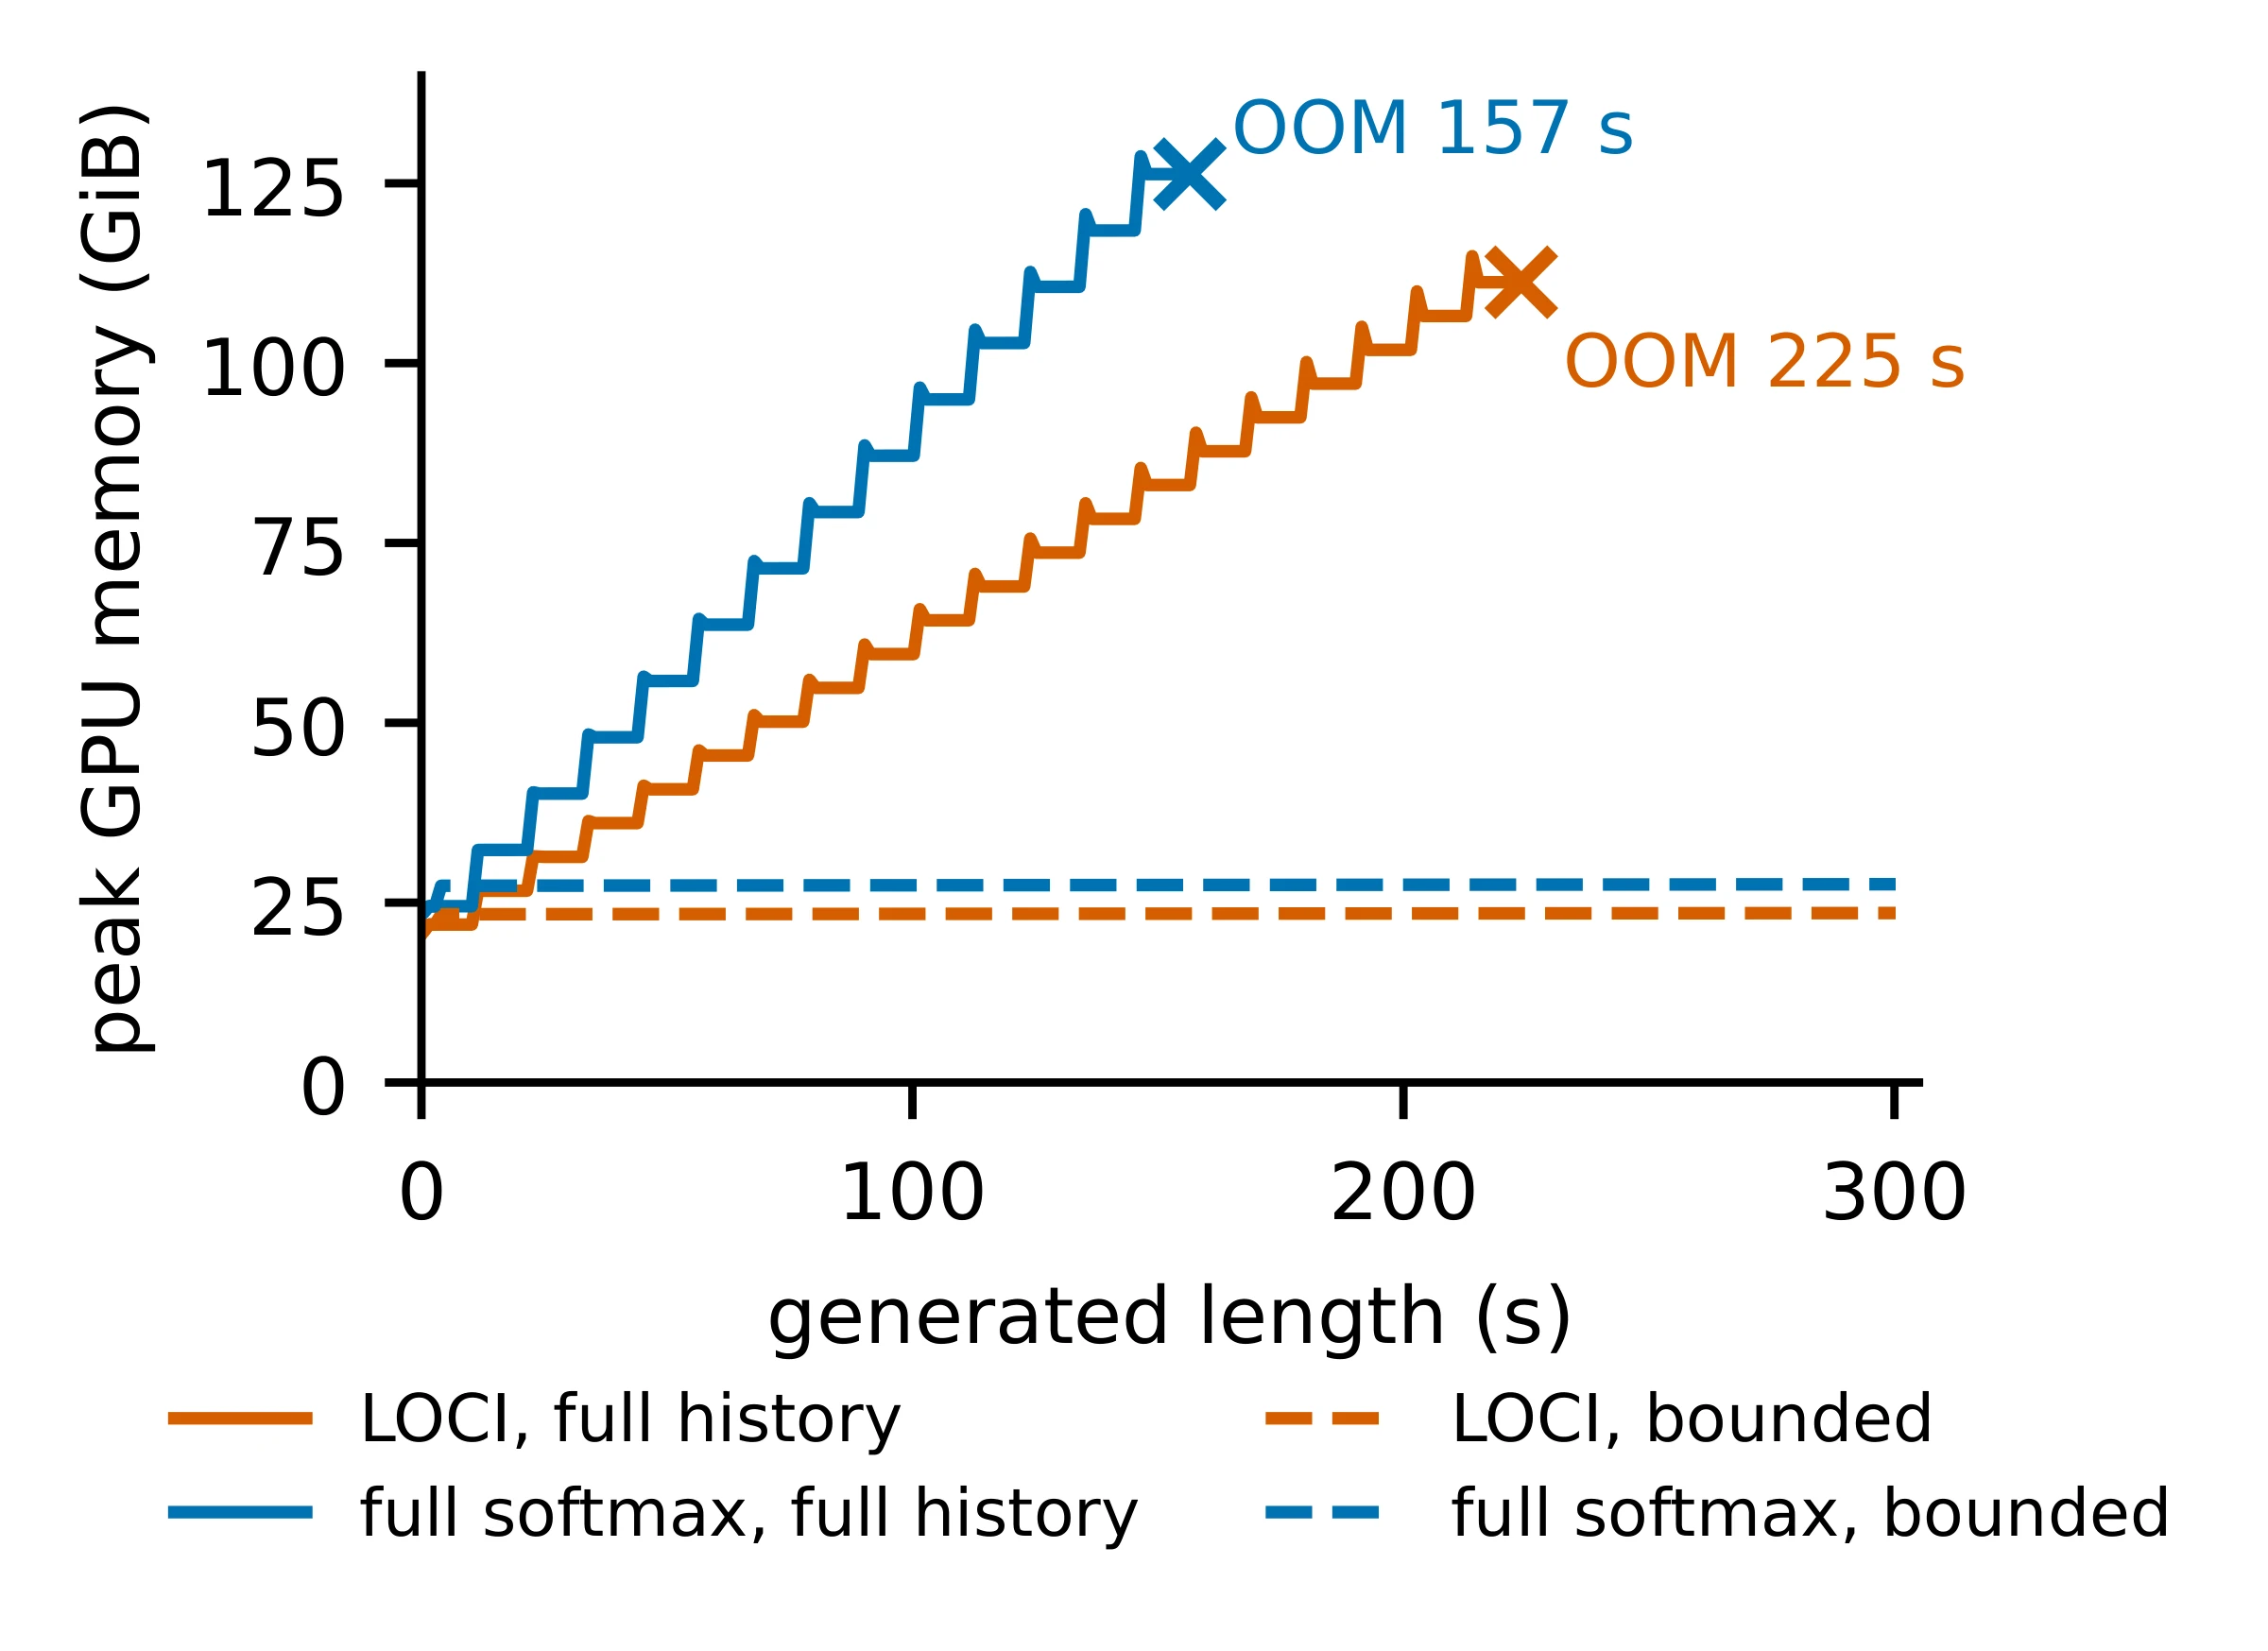
- lower peak memory than full softmax at equal length, full history; reachable length 157 s → 225 s
- 300s
- streamed at a constant 23.6 GiB with bounded sparse access
Scroll to move the camera
Start here.
Then. Now.
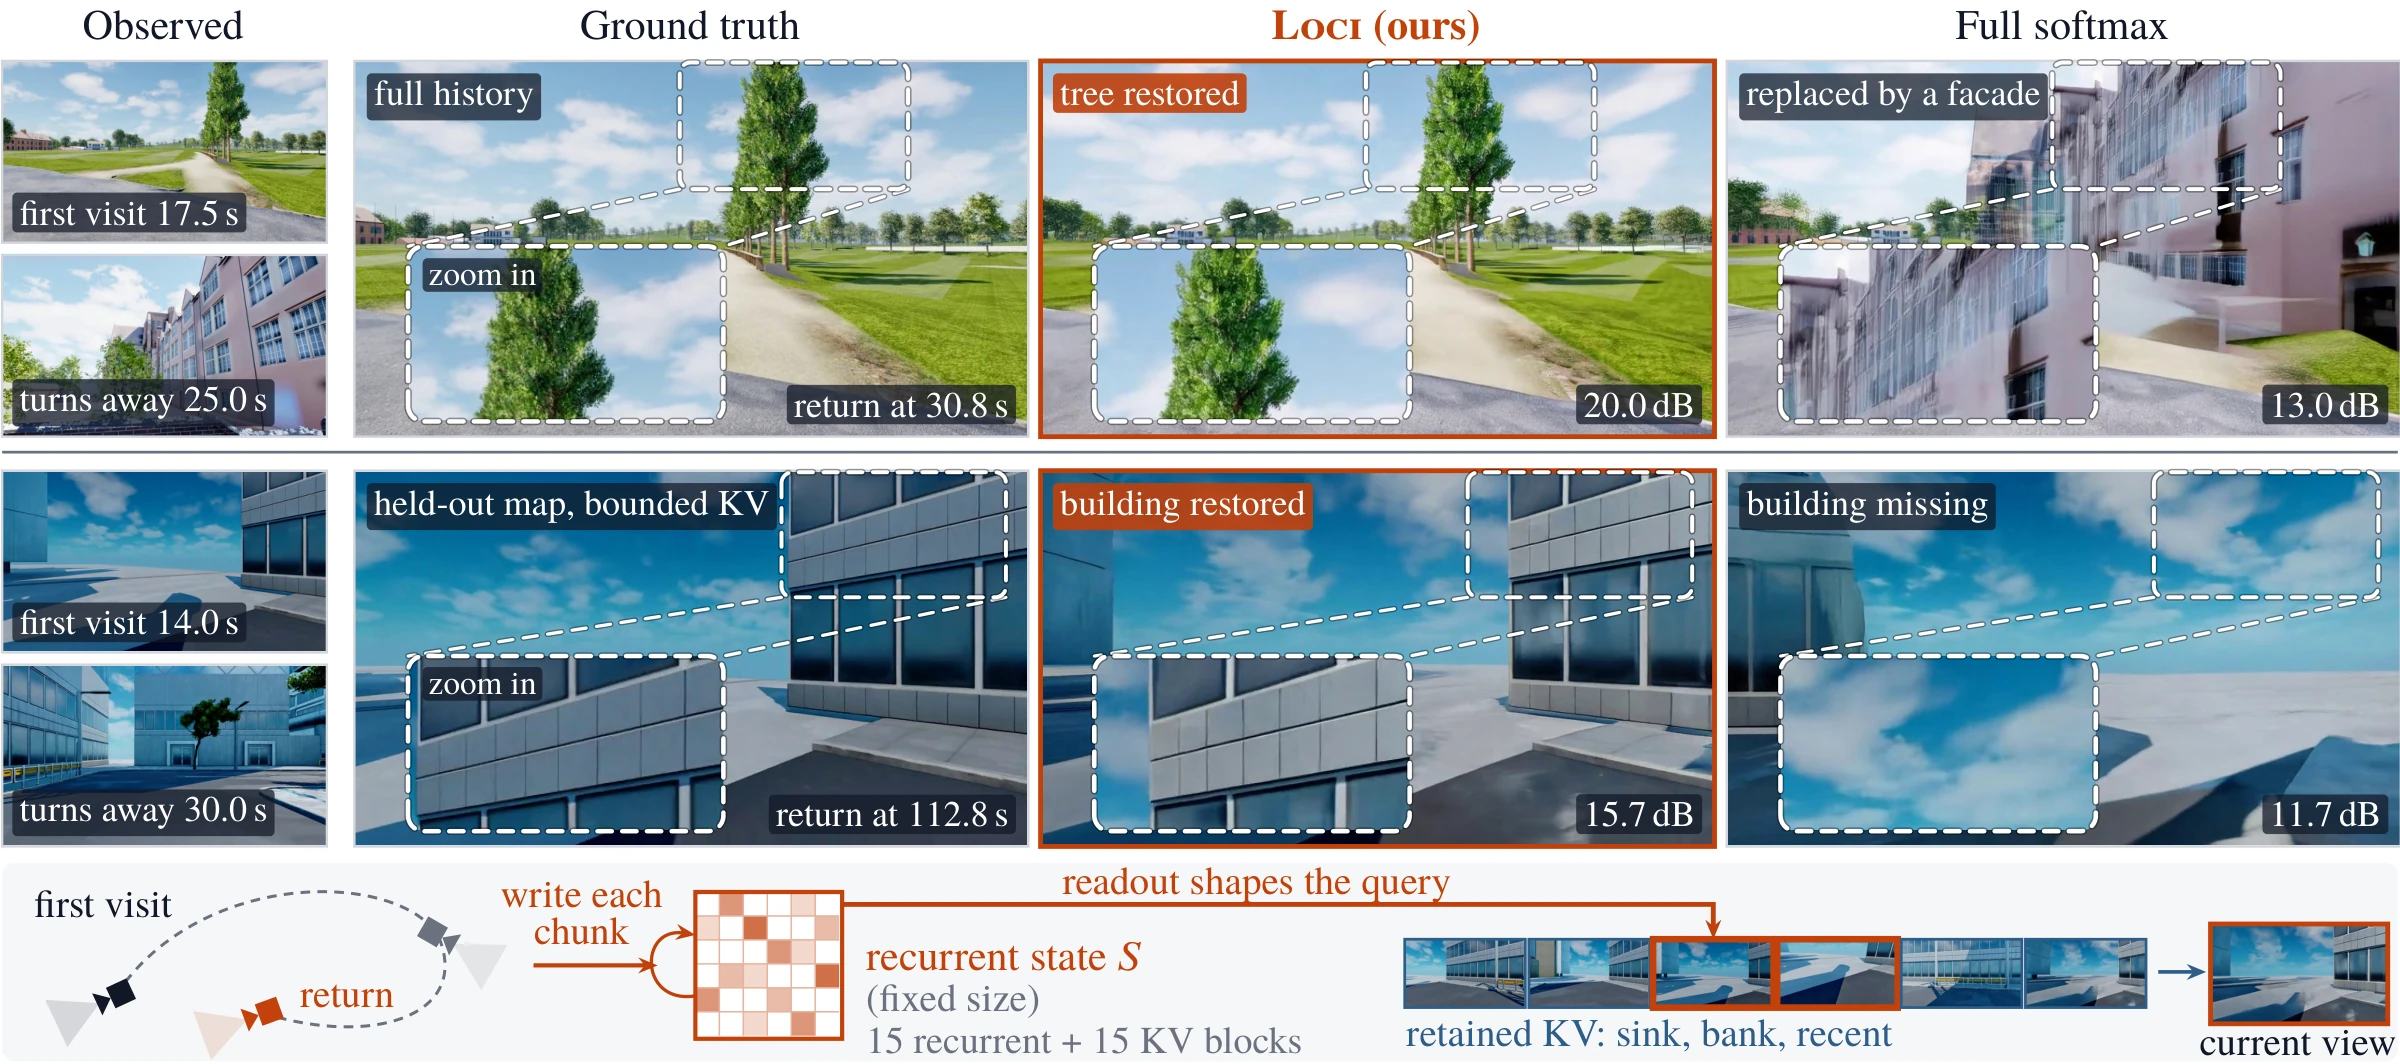
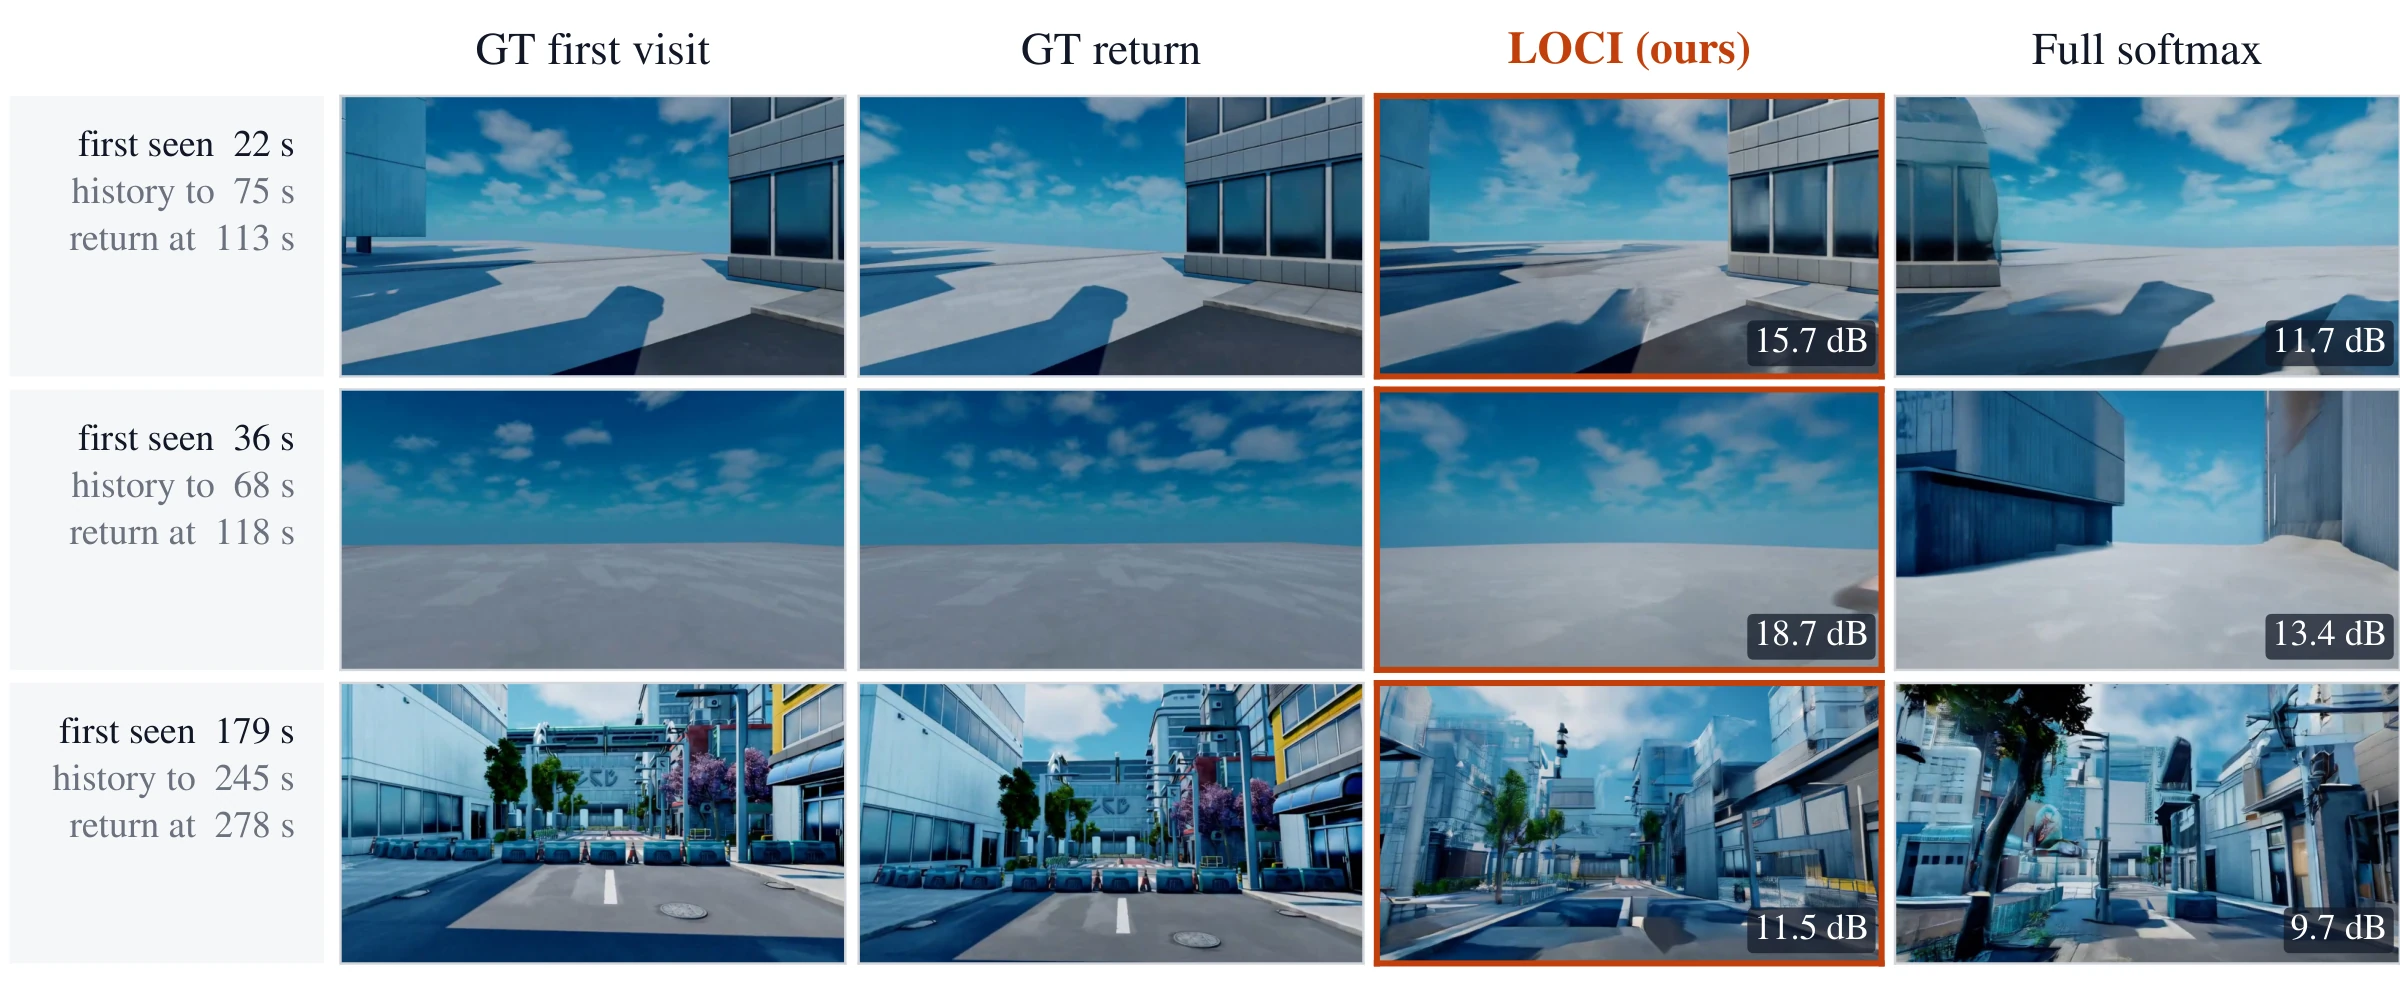
Same camera pose, a minute apart. On the left, the first time the model drew the view. On the right, the view after a full turn and a walk. Drag to compare.
Method
Two traces of the past. Working together.
A camera-conditioned recurrent state summarizes the whole history at fixed size, while retained key–value (KV) features preserve observation-level evidence; the recurrent readout then guides attention toward the relevant retained views.
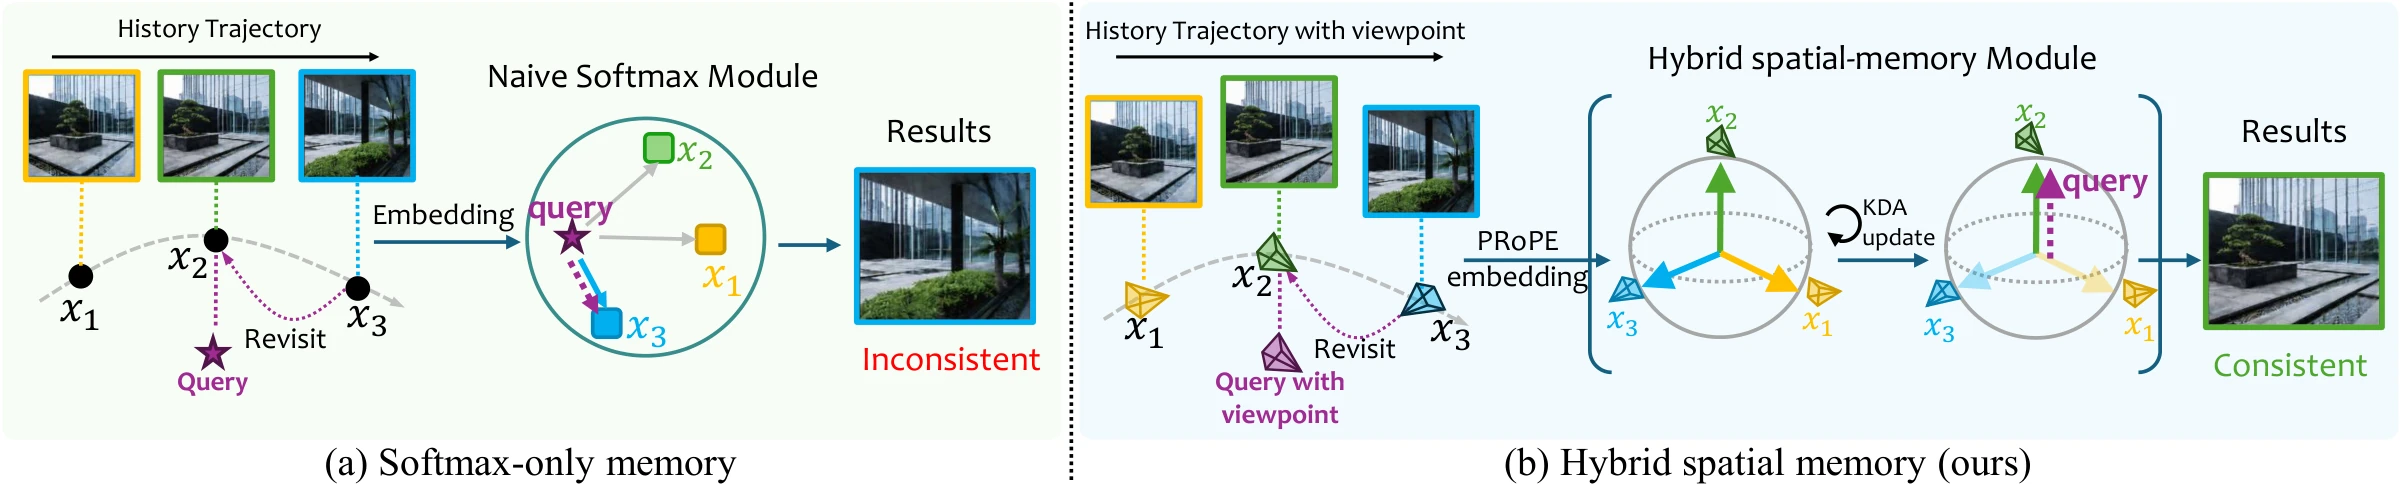
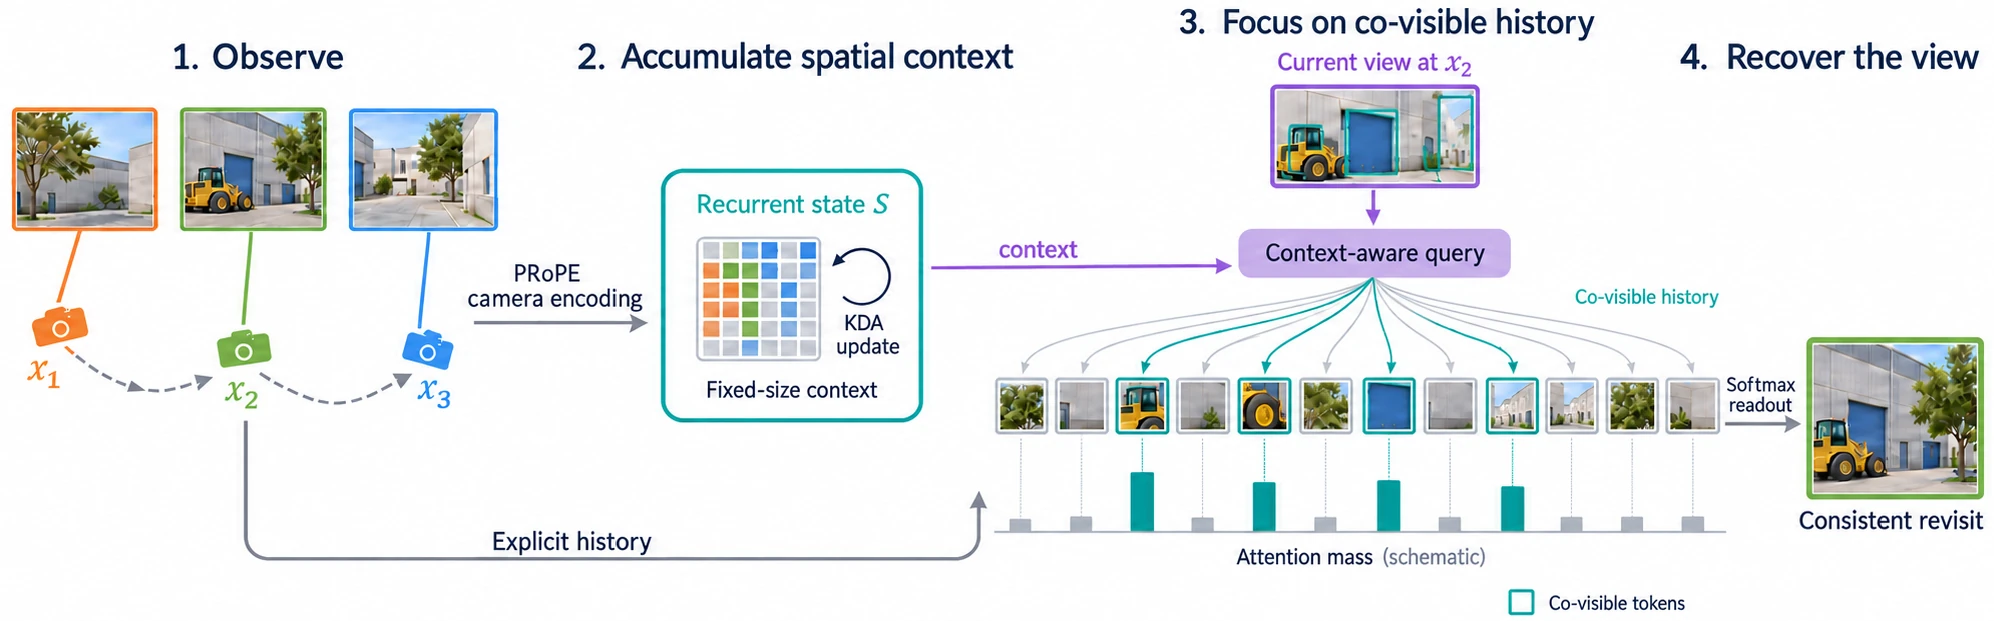
- Hybrid layoutFifteen blocks add recurrent Kimi Delta Attention (KDA); fifteen keep softmax attention over retained keys and values.
- Projective camera encodingPRoPE conditions the recurrent memory on each token's camera ray, so reads depend on viewpoint.
- Chunk-synchronous memoryWrites use the delta rule; retention is applied once per chunk, so forgetting follows elapsed video time.
- Dense or bounded historyBounded mode attends to at most 34 latent frames, while the recurrent state carries the whole history.
What it keeps.
A fixed-size recurrent state takes in every frame; a bounded set of retained frames keeps sharp detail of the views that cover the scene best.
- Sink frameThe first view. Always kept.1
- AnchorsEarly views, pinned and never dropped.0
- Coverage bankOlder views chosen to cover the scene, up to 20.0
- Recent windowThe last 8 frames, for smooth motion.0
- Recurrent stateKDA layers fold every frame into a fixed-size state, read through camera geometry.0
Results
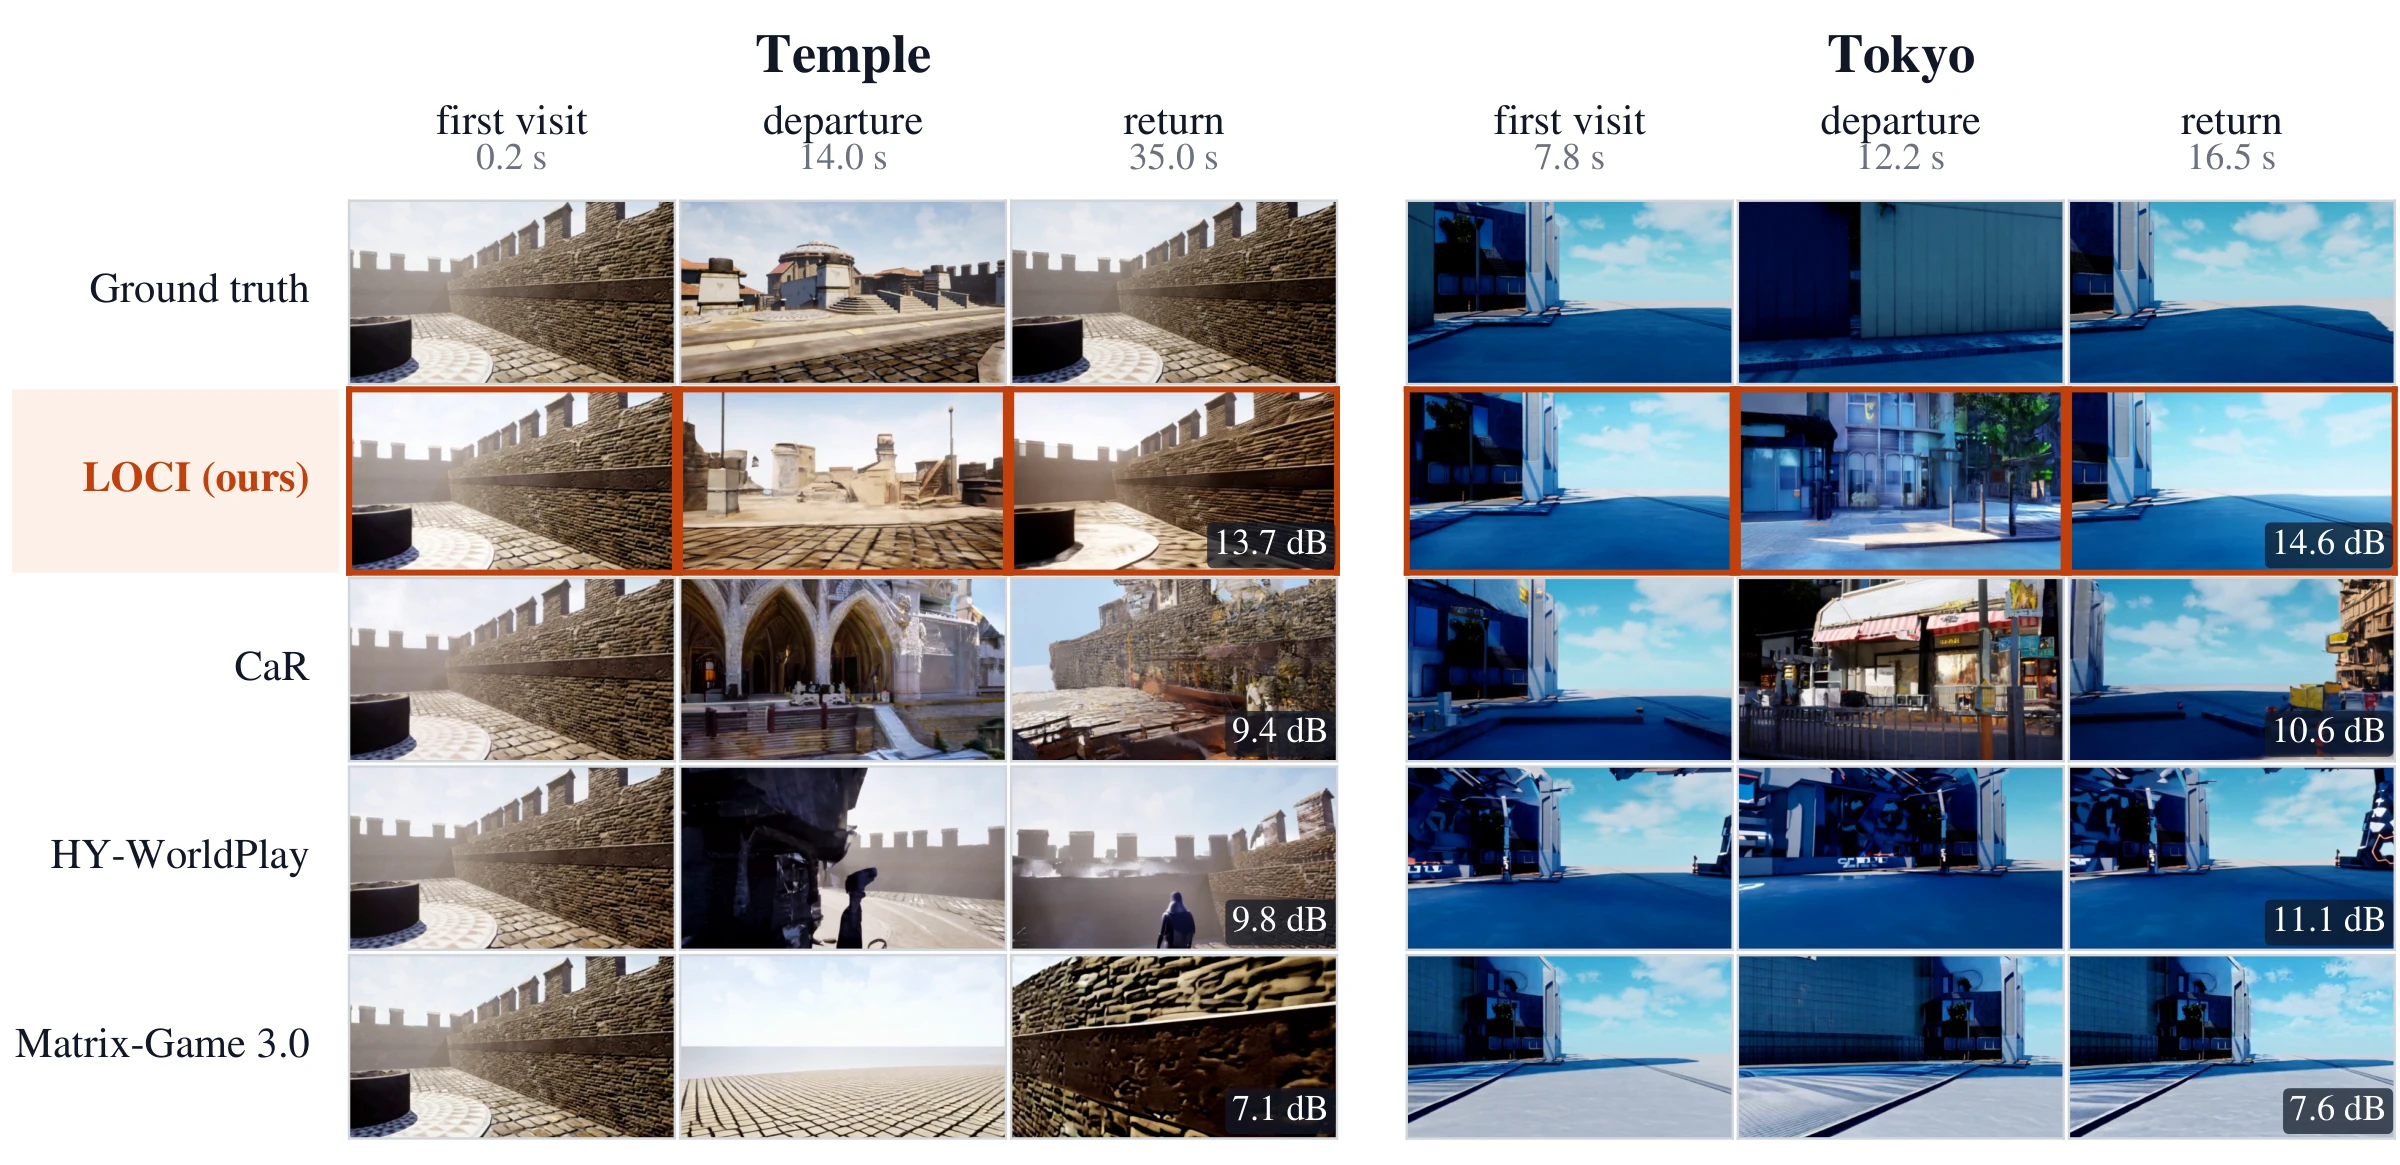
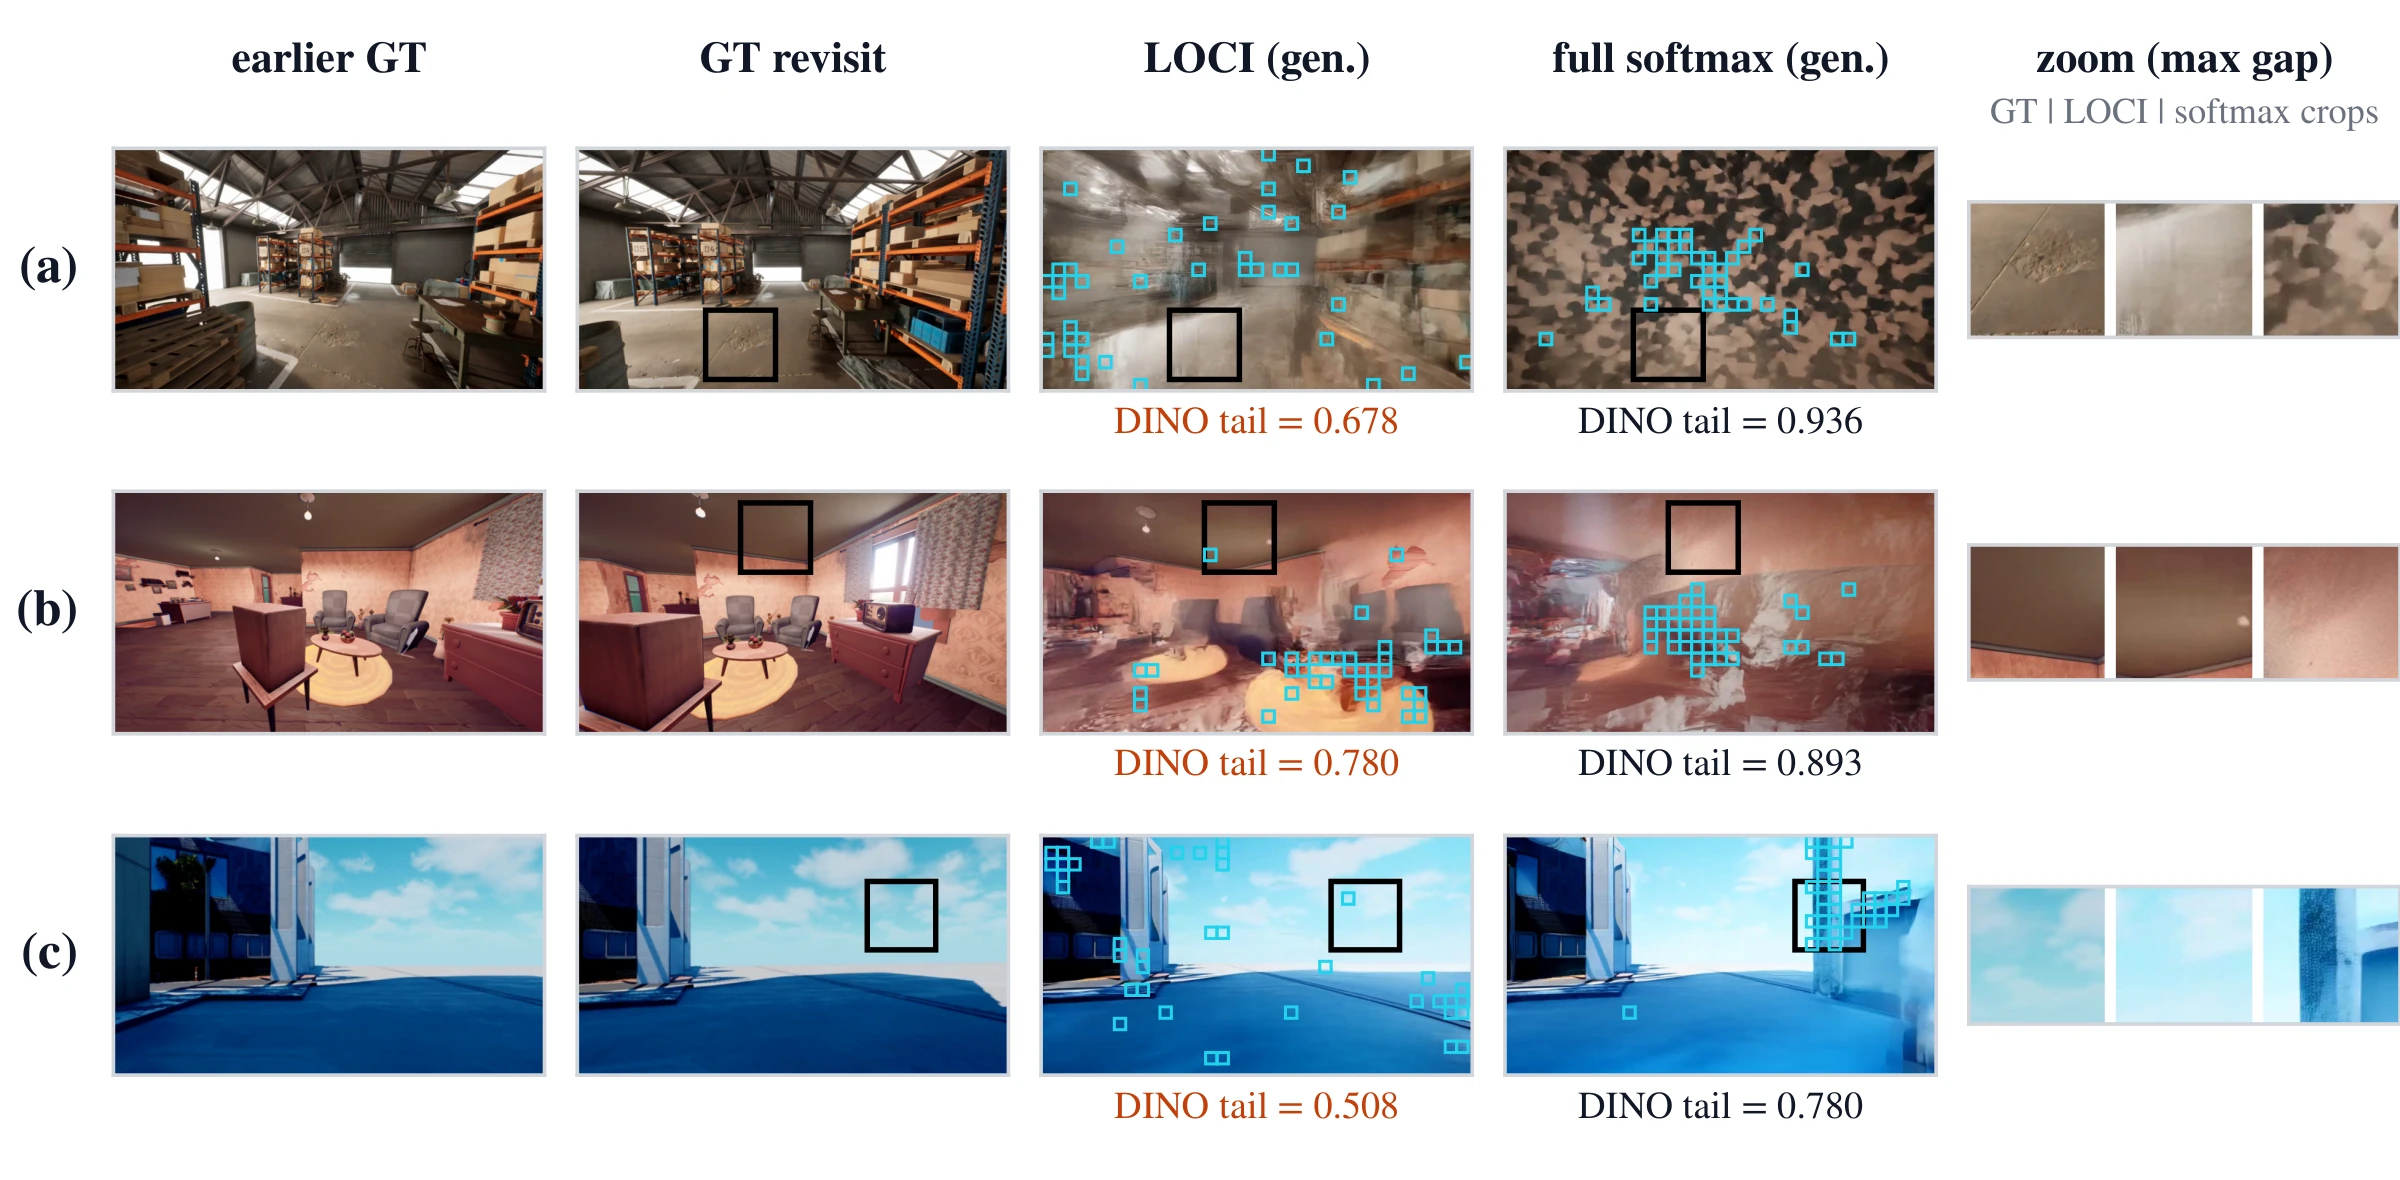
Revisits, measured. Against the recording.
Evaluated zero-shot on the MIND memory test over the entire prediction segment; full softmax is the same backbone and recipe with softmax attention in all 30 blocks. Protocol details are in the paper.
MIND memory test
| Method | Params | Trained on MIND | n | MSE ↓ | PSNR ↑ | SSIM ↑ | LPIPS ↓ |
|---|---|---|---|---|---|---|---|
| Reference (reported in the GIM-World paper) | |||||||
| SSM | – | ✓ | – | 0.0796 | 11.96 | 0.395 | 0.744 |
| FramePack | – | ✓ | – | 0.0764 | 12.04 | 0.376 | 0.706 |
| Context-as-Memory | – | ✓ | – | 0.0706 | 12.50 | 0.392 | 0.695 |
| GIM-World | 1.3B | ✓ | – | 0.0614 | 13.40 | 0.414 | 0.630 |
| Run by us (entire prediction segment) | |||||||
| HY-WorldPlay | 8B | × | 50 | 0.0710 | 12.54 | 0.398 | 0.715 |
| Matrix-Game 3.0 | 5B | × | 49 | 0.0866 | 11.69 | 0.373 | 0.666 |
| AlayaWorld | 15B | × | 50 | 0.0908 | 11.33 | 0.358 | 0.683 |
| Alaya-EVOKE | 14B | × | 50 | 0.0884 | 11.14 | 0.347 | 0.710 |
| LingBot-World | 28B | × | 50 | 0.0955 | 11.33 | 0.331 | 0.703 |
| CaR‡ | 5B | × | 36 | 0.0538 | 13.85 | 0.458 | 0.622 |
| LOCI (ours) | 5B | × | 50 | 0.0455 | 14.36 | 0.464 | 0.643 |
| LOCI (bounded sparse) | 5B | × | 50 | 0.0622 | 13.02 | 0.409 | 0.679 |
LOCI is best among the models we ran; reference rows are as reported in the GIM-World paper. ‡CaR: 36 shortest segments only.
Hybrid vs. full softmax, same backbone, data and recipe
| Data mixture | History | n | PSNR ↑ | LPIPS ↓ | ||||
|---|---|---|---|---|---|---|---|---|
| Softmax | LOCI | Δ [95% CI] | Softmax | LOCI | Δ [95% CI] | |||
| Uniform | bounded | 50 | 12.17 | 12.85 | +0.67 [+0.42, +0.93] | 0.700 | 0.680 | −0.020 [−0.028, −0.011] |
| UE-weighted | bounded | 50 | 12.13 | 13.02 | +0.89 [+0.64, +1.15] | 0.704 | 0.679 | −0.024 [−0.034, −0.015] |
| UE-weighted | full | 32 | 13.90 | 14.25 | +0.35 [+0.08, +0.62] | 0.669 | 0.641 | −0.029 [−0.040, −0.018] |
Paired differences (LOCI − full softmax) with 95% bootstrap intervals.
Long-horizon generation and cost
Replacing half of the historical-KV layers with recurrent state extends the reachable length from 157 s to 225 s. Under bounded sparse access, LOCI runs the full 300 s at a constant 23.6 GiB.
Any world. Same memory.
Each world starts from a single image: a photograph, an engine render, or a generated painting. Open one to watch it explored along several camera paths.
Data
Training data
Unreal Engine scenes and CARLA towns that we rendered, plus real walking videos from Sekai. No MIND clips are used.
Held-out recorded trajectories
Held-out 40 s walk-through clips that repeatedly return to earlier viewpoints.
Live. On one GPU.
A 4-step distilled student streams the world as you steer it. This clip is a recording of the interactive demo: the keys lit below are the ones that were held.
Read more.
BibTeX
@article{xia2026loci,
  title={LOCI: Spatial Linear Memory for Streaming World Models},
  author={Xia, Ji and Liao, Tingting and Liang, Xuezhi and Li, Hao and Liu, Guangyi},
  journal={arXiv preprint arXiv:2609.40222},
  year={2026}
}